
Microservices vs. Monoliths: A Practical Overview
Microservices are often presented as the default choice for cloud-native systems, but they are not a silver bullet. They solve a specific set of problems, mostly organizational ones, and they charge a real price in distributed-systems complexity. This post walks through what actually separates a monolith from microservices, when the trade is worth making, and the design practices (decomposition, state management and the 12-Factor App) that keep a microservices system healthy once you commit to it.
The real difference is the deployment boundary
A monolithic application packages all features into a single codebase, typically shares a single database, and is deployed as one unit. A microservices architecture splits that same application into smaller, independent services. Each one has a clearly defined responsibility, can be deployed on its own, typically owns its own datastore, and talks to the others through APIs.
It is tempting to frame this as "messy monolith vs. clean microservices", but that misses the point. Both architectures should follow strong modular design principles. A well-built monolith has clear modules with well-managed interfaces between them. The main distinction is not modularity. It is the deployment boundary. In a monolith, modules ship together. In microservices, modules are independently deployable.
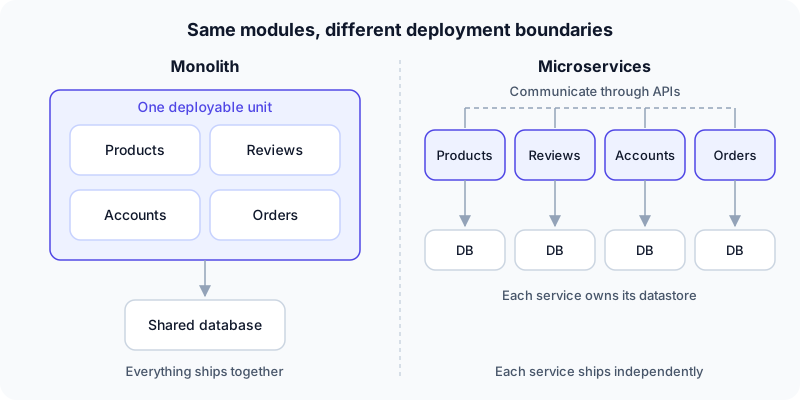 Same modules, different deployment boundaries
That single difference drives almost every benefit and every cost that follows.
Why teams choose microservices
The primary reason microservices are popular is organizational scalability. Imagine a company that grows from one team of eight engineers to six teams of eight. With a monolith, all six teams funnel their changes through one build and one deployment pipeline. A bug in the reviews feature can block a release of the checkout flow, and release day becomes a coordination exercise. With microservices, each team deploys at its own cadence, so adding more teams can actually increase delivery velocity instead of creating a bottleneck around a single pipeline.
Independent deployment unlocks a set of secondary benefits. You can scale each service independently, giving more instances to the busy product catalog and fewer to the rarely used admin tools, which in turn gives you fine-grained cost control and cost accounting per service. Observability and logging get clearer boundaries, because a failing service is a named, isolated thing. Each service can roll back on its own release cycle without touching the others, and you can run A/B tests at the subsystem level.
What you pay for it
Distributed systems are inherently more complex than monoliths, and microservices make you pay that complexity up front. Defining clear service boundaries is genuinely difficult, and a wrong boundary is far more expensive to fix across a network than inside one codebase. Infrastructure complexity grows, because every service needs its own build, deployment, monitoring and configuration. Every network hop is a new failure point and adds latency. Service-to-service calls need to be secured. And because services deploy independently, APIs need deliberate versioning and backward compatibility: you can no longer change a function signature and fix every caller in the same commit.
| Monolith | Microservices | |
|---|---|---|
| Deployment | All modules ship together | Each service ships independently |
| Data | Typically one shared database | Each service owns its datastore |
| Scaling | Scale the whole application | Scale each service on its own |
| Main cost | Coordination as teams grow | Distributed-systems complexity |
The architectural overhead has to be justified by real organizational or scaling needs. If one team owns the whole product, a modular monolith is often the better answer.
Decomposing the application
Deciding where to cut is one of the hardest design tasks, and domain-driven design (DDD) is the most useful tool for it. DDD helps you identify logical functional groupings based on business domains rather than technical layers. In an online retail application, those domains might be product management, reviews, accounts and orders. Each grouping becomes an application exposing APIs, and internally each one may consist of several microservices organized by architectural layer.
Shared capabilities such as authentication should be isolated and deployed as their own services rather than copied into every domain. The guiding goal is to minimize dependencies between services and maximize cohesion within them. If two services always have to change and deploy together, the boundary between them is probably in the wrong place.
The same independence rule applies to data: each microservice should own its datastore. Sharing a database between services reintroduces tight coupling through the back door. One team's schema change can silently break another team's service, and you are back to coordinated releases.
Stateless services, isolated state
A stateless service does not keep client state in memory. It retrieves state from external systems. That makes it easy to scale horizontally, easier to upgrade, more fault tolerant, and free of sticky sessions, because any instance can serve any request. At some point, though, most applications need stateful components, and those are harder to scale, more complex to upgrade, and carry more operational overhead.
The practical approach is to keep state out of the places that need to scale. Avoid shared in-memory state: it prevents effective autoscaling and forces the load balancer to use session affinity (sticky sessions). Instead, push state into backend storage services, such as persistent storage like Cloud SQL or Firestore, and a caching system such as Redis (for example, Memorystore). Your frontend services stay stateless and scalable, and the complexity of state is confined to specific, well-understood parts of the architecture.
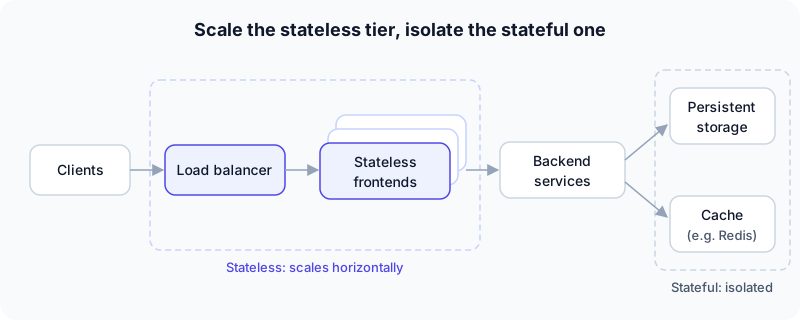 A common layout: scale the stateless tier freely, isolate the stateful one
Put together, a common layout looks like the diagram above: a load balancer distributes traffic, stateless services scale independently, and stateful services are isolated behind persistent storage and caching. This design maximizes cloud-native scalability and fault tolerance.
On Google Cloud, several compute platforms suit this model, each with a different balance of control and abstraction: App Engine, Cloud Run, Google Kubernetes Engine (GKE) and Cloud Run functions.
The 12-Factor App
The 12-Factor App is a methodology that defines twelve best practices for building SaaS and cloud-native systems, with an emphasis on portability, scalability and continuous deployment. It predates the microservices trend, but it fits it almost perfectly, because each factor removes something that would otherwise tie a service to one machine, one environment or one deployment.
| # | Factor | What it means in practice |
|---|---|---|
| 1 | Codebase | One codebase per service, tracked in version control such as Git |
| 2 | Dependencies | Declared explicitly with the language's dependency manager, isolated in containers, images stored in a registry |
| 3 | Config | Kept outside the code, typically in environment variables, so the same build runs in dev, test and prod |
| 4 | Backing services | Databases, caches and queues treated as attached resources, reached through configuration (URLs) |
| 5 | Build, release, run | Three separate stages: build the artifact, combine it with config into a uniquely identified release, then run it |
| 6 | Processes | Apps run as stateless processes, with state kept in external services such as per-service datastores and caches |
| 7 | Port binding | The web server is bundled into the app, which exposes itself on a port (Compute Engine, GKE, App Engine, Cloud Run) |
| 8 | Concurrency | Scale horizontally by adding or removing processes as demand changes |
| 9 | Disposability | Fast startup, graceful shutdown and tolerance of infrastructure failures, so the platform can scale up and down quickly |
| 10 | Dev/prod parity | Development, staging and production kept consistent with containers, infrastructure as code and automated provisioning |
| 11 | Logs | Treated as event streams written to standard output, aggregated and analyzed outside the application |
| 12 | Admin processes | One-off tasks run separately, automated and repeatable, using scheduled jobs or task systems |
Read as a whole, the factors cluster around a few ideas. The first five make a service reproducible: the same code and dependencies, built the same way, configured from the outside, can be promoted from one environment to the next without changes. Factors six to nine make it elastic: stateless, self-contained processes that start fast and die gracefully are exactly what an autoscaler needs. The last three make it operable: environments that behave alike, logs a platform can collect, and maintenance tasks that don't depend on someone remembering the right commands.
Followed consistently, these practices deliver much of what microservices promise: independent deployment, horizontal scalability, portability across environments, improved reliability, simpler CI/CD pipelines, and strong environment consistency.
Wrapping up
Microservices are not simply a technical trend. They are an organizational scaling strategy. They let independent teams release faster and scale parts of the system on their own, but they bring network latency, more failure points, infrastructure overhead and strict API governance. Adopt them when organizational growth, the need for deployment independence, real scalability constraints and your long-term operational strategy justify that cost. Whichever way you go, strong modular design is non-negotiable: clearly defined boundaries and well-managed interfaces are what make either a monolith or a microservices system succeed.