
Logging and Monitoring
At some point something will break, slow down or look suspicious, and the first question will be "what happened?" Logging and monitoring are how you answer it. They give you visibility into what is happening inside your Google Cloud environment, and you need them for troubleshooting, performance tuning, security investigations and everyday operational awareness.
Google Cloud provides native services for both through Cloud Operations: Cloud Logging for logs and Cloud Monitoring for metrics. In the resource hierarchy post you created shared projects for logging and monitoring. This post explains what flows into them and how to set that flow up.
How Cloud Logging collects logs
Cloud Logging collects and stores logs generated by Google Cloud services and by your workloads. Many services, such as Compute Engine and GKE, generate logs automatically. What happens inside a virtual machine is different: operating system and application logs from VMs are only collected once the Ops Agent is installed.
Beyond collection, Cloud Logging lets you ingest OS and application logs, search and analyze logs in near real time, create log-based metrics, and export logs to external destinations. Those last two capabilities become important later, because they are how logs feed monitoring and how they leave a single project.
By default, logs are created and stored at the project level. That is a sensible default for one team with one project, and a real problem for an organization with hundreds of them, as you will see below.
The logs that matter
Not all logs answer the same questions. It helps to group them by what they tell you.
Google Cloud audit logs record actions performed on your resources. There are four kinds. Admin Activity logs capture configuration changes and are always enabled. Data Access logs record data read and write operations and are usually disabled by default. System Event logs record actions Google Cloud itself takes on your resources. Access Transparency logs show when Google personnel access customer data for support purposes.
Admin and user audit logs track changes made through identity and administration systems: user creation, group updates, security configuration changes. These are the trail of everything you did in the earlier posts of this series. Because retention in the Admin Console is limited, exporting these logs is recommended for compliance and auditing.
Ops Agent logs give you visibility inside virtual machines: system logs and application logs from things like web servers and databases. Without them you can see that a VM is running, but not why the application on it is returning errors.
Network logs show traffic and connectivity. VPC Flow Logs capture network flow metadata, firewall rule logs show which traffic was allowed or denied, and Cloud NAT logs track outbound internet connectivity. After the networking and hybrid connectivity posts, these are your main tools for answering "why can't A reach B?"
Security analyst: Who changed this firewall rule last night?
Platform engineer: Admin Activity logs will tell us who and when. Firewall rule logs will tell us what traffic it let through afterwards.
Retention and cost
Different log types come with different retention periods and cost models, and that should influence what you enable.
| Log type | Retention | Cost |
|---|---|---|
| Admin Activity logs | 400 days | Free |
| Data Access logs | 30 days | Charged by volume |
| Network logs (e.g. VPC Flow Logs) | 30 days | Charged by volume |
| Ops Agent logs | 30 days | Charged by volume |
The pattern is clear: the record of configuration changes is kept for over a year at no cost, while high-volume operational logs are kept for thirty days and billed by volume. Keep that in mind with Data Access logs, which are usually disabled by default. Turning them on everywhere can produce a lot of billable data, while turning them on for the projects that hold sensitive data is usually the better balance. And if you need anything for longer than thirty days, plan to export it.
Metrics and Cloud Monitoring
Logs describe individual events. Metrics are numerical time series, such as CPU utilization or request latency over time, and they are stored in Cloud Monitoring, where they power dashboards and alerts.
There are three main categories of metrics: Google Cloud metrics collected automatically by the platform, agent metrics collected by the Ops Agent from virtual machines, and custom metrics defined by your applications and workloads. Log-based metrics, created in Cloud Logging, add a fourth source by turning matching log entries into a number you can chart and alert on.
The monitoring workflow usually follows the same four steps:
- Metrics are ingested from services and agents.
- You explore them with Metrics Explorer.
- You build dashboards to visualize system health.
- You configure alerts that notify teams when thresholds are exceeded.
Two concepts come up constantly while doing this: the resource type (what is being measured, such as a VM instance) and the metric type (what is measured about it, such as CPU utilization). Getting comfortable with both makes Metrics Explorer, and every alert you write, much easier.
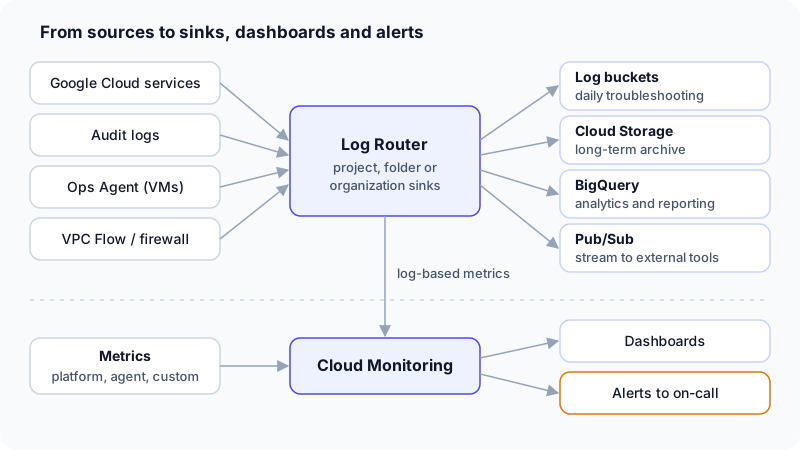 Logs go through the Log Router to their destinations, while metrics, including log-based metrics, feed Cloud Monitoring
Centralizing logs with the Log Router and sinks
Logs are generated per project, but they do not have to be managed per project. Every project includes a Log Router, and by default logs stay in the project where they were generated. Sinks change that: a sink copies matching logs to a central destination.
Sinks can also be created at the folder or organization level. A folder-level sink can aggregate logs from all its child projects, and an organization-level sink collects logs from the entire organization. This is where the hierarchy you designed earlier pays off again: one sink on the production folder captures every production project, including ones created next month.
Imagine a security team investigating an incident that touches twelve projects. Without centralization, they need access to twelve projects and twelve separate searches. With an organization-level sink feeding the shared logging project, they search one place, with logs from every project already collected side by side. That is why this approach is common for security, compliance and long-term retention.
Choosing log destinations
A sink needs a destination, and each one serves a different purpose. Log buckets are best for daily troubleshooting, since you keep searching in Cloud Logging. Cloud Storage is best for long-term archival, for example keeping audit logs beyond their default retention. BigQuery is best for analytics and reporting, when you want to query logs with SQL across months of data. Pub/Sub is best for streaming logs to external systems such as a third-party SIEM.
You are not limited to one. A common setup sends everything to a central log bucket for troubleshooting and also sends audit logs to Cloud Storage for compliance.
Tip: Decide retention requirements first, then pick destinations. "We need audit logs for several years" points straight to an export. Nobody wants to discover a thirty-day limit during an audit.
Wrapping up
Cloud Logging and Cloud Monitoring give you two views of the same environment: logs tell you what happened, metrics tell you how things are behaving over time. Know which logs exist and what they cost, install the Ops Agent where you need visibility inside VMs, and enable Data Access logs deliberately. Then use the Log Router with folder- or organization-level sinks to bring logs into the shared logging project, choose destinations by purpose, and build dashboards and alerts on top of your metrics. With visibility in place, the last piece of the foundation is putting guardrails around it, which is the subject of the next post on organizational security.